Delete and Reorder PDF Pages Free
Put PDF pages in the order you actually want, without installing anything. Drag thumbnails into place, delete the pages you don't need, and export a lossless PDF. No upload, no signup, and your file never leaves your device.
Reorder your PDF pages
Drop a PDF here
One file at a time: every page becomes a card you can drag
The PDF is opened on this device only. Nothing is uploaded.
Drag a page card to a new spot, or use the ↑ ↓ buttons on each card. The ✕ button removes a page from the output only; your original file is never modified. Reordering and deleting work before you export, so you can tinker as long as you like.
PDF Reorder — illustrated, step by step
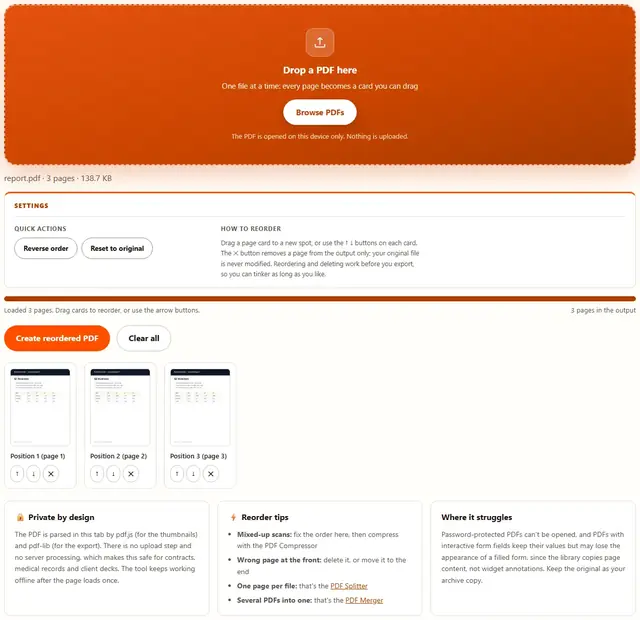
How to reverse PDF page order or delete pages
Three steps, about a minute, no technical skills needed.
Add your PDF
Drop a PDF on the dropzone or click Browse. The tool renders a small thumbnail for every page so you can see what each page is, with a progress bar while they draw.
Drag pages into order
Rearrange the page cards by dragging, or use the up and down buttons on each card. The ✕ button deletes a page from the output only. Reverse order and Reset to original are one click away if you overshoot.
Download the reordered PDF
Click Create reordered PDF. The new file keeps your original quality and downloads as name-reordered.pdf, so your original stays untouched.
Why reorder in the browser?
Because there is no upload step, page reordering here is safe for contracts, tax documents, medical paperwork and anything under NDA. The file never leaves the device you're sitting at, and there is no queue, no account and no file-size ceiling beyond your own memory. Details in our file-handling policy.
Troubleshooting
Will reordering pages reduce the quality of my PDF?
No. The tool never re-renders or re-compresses your pages: it copies the existing page objects into a new file in the order you chose, so text stays selectable and images stay exactly as they were. The only things that change are the order, and any pages you deleted.
Can I delete pages instead of extracting the ones I want?
Yes, and for most jobs it is faster. Remove the pages you don't need with the ✕ button and the rest stay in place, then export. If you only want a handful of pages out of a long document, the range box in the PDF Splitter does that in one step.
The thumbnails are blank or never finish rendering
Very large scans take a while to draw, and a few PDFs use image encodings some browsers handle poorly. Wait for the status line to finish. Even if a thumbnail stays blank you can still move that page by its position number and export, because the export step works on the original page data, not on the preview.
My PDF asks for a password
Password-protected files can't be opened by any browser tool, including this one. Remove the password in your PDF app first, or use Print to PDF to produce an unlocked copy, then reorder that copy here.
Are my PDFs uploaded?
No. The file is read in this browser tab: pdf.js draws the thumbnails and pdf-lib assembles the new file locally. Nothing is sent to a server, and the DevTools Network tab stays empty while you reorder. Details are in our file-handling policy.
How do I move one page to the very end?
Either drag its card to the last position, or press the ↓ button until it lands there. Every card also has ↑ and ↓ buttons, so the whole tool works with a keyboard or screen reader without any dragging at all.
The downloaded PDF is smaller than the original: did something get lost?
Usually nothing visible was lost. Saving through pdf-lib drops cached thumbnails and rebuilds the file structure, which often shrinks the file. If your original contained embedded attachments, keep the original file as your archive copy.
Can I reverse the page order of a PDF?
Yes. Drag the last thumbnail to the front, or delete the pages you do not need and arrange the rest in any order before you export. The new PDF keeps the order you set, and the original file is never changed.
Why page order matters more than people expect
Most PDF complaints are really order complaints in disguise. A scanner feeds pages out of sequence and nobody notices until the filing deadline. A contract arrives back with the signature page stapled in the middle. A teacher assembles a packet from three sources and the answer key ends up on page two. In each case the content is fine and the sequence is wrong, which is exactly the problem a PDF reorder tool should solve without touching anything else.
Order changes how a document reads, and how it is judged. Reviewers skim in sequence. Printers impose pages in sequence. Recruiters see what you put first. Moving an appendix to the back or a summary to the front is a one-minute edit here, and it is the cheapest form of document improvement there is: no rewriting, no reformatting, no export dance through a desktop suite.
The tool works on the page level, not the pixel level. Each card in the grid represents one page of your file, shown at thumbnail size with its original page number underneath, so "Position 3 (page 14)" tells you exactly where page 14 of your source file is going. That label matters when you are fixing a 60-page scan and need to trust what you are doing.
| Part of the file | Original PDF | After reordering |
|---|---|---|
| Page order | As authored or scanned | Exactly the order you arranged |
| Text and images | Stored objects | The same objects, copied in a new sequence |
| Page dimensions | Mixed sizes allowed | Each page keeps its own size |
| Quality | Original | Unchanged: nothing is re-rendered or re-compressed |
| File size | Baseline | Often slightly smaller, because the rewrite drops cached thumbnails |
How the reorder tool works under the hood
Two well-known open-source libraries do the work, both loaded on demand and both running inside your tab. pdf.js (Mozilla's renderer, the same engine behind the Firefox PDF viewer) opens the file and draws each page to a tiny canvas so you can see what you are moving. pdf-lib then builds a fresh document by copying the page objects you kept, in the sequence you chose, and saves it as a new PDF.
Because the pages are copied rather than photographed, text remains real text: you can still select it, search it and copy from it in the output. Links, bookmarks within copied pages and embedded fonts travel along with the page objects. This is the same lossless mechanism the PDF Splitter and PDF Merger use, which is why all three tools produce files that behave like the original in every way except the arrangement.
Thumbnail rendering happens page by page with a progress bar, so a 200-page document tells you where it is instead of freezing the tab. The export step is a single pass: choose the kept pages, copy, save, hand you a download named name-reordered.pdf. If anything fails, such as a corrupted file or an encrypted one, the status line says what happened rather than leaving a spinner running.
Reorder, split or merge: which page tool do you actually need?
All three BeeToolify page tools are lossless and local, but they solve different shapes of problem. Reordering fixes a sequence inside one file. Splitting takes pieces out. Merging brings files together. Picking the right one saves you from doing two jobs in one tool.
| Situation | Right tool | What you get back |
|---|---|---|
| Scanned pages came out in the wrong order | PDF Reorder Number Pages | The same file, rearranged and optionally slimmed by deletions |
| You need pages 4 to 7 out of a 90-page report | PDF Splitter | A short PDF containing just that range |
| Every page must become its own file | PDF Splitter | One single-page PDF per page |
| Three scans (invoice, receipt, proof) must be one attachment | PDF Merger | One combined PDF in the order you stacked them |
| Both the order and the file size need fixing | Reorder, then PDF Compressor | Correct sequence, then a lighter file |
A common real-world chain is scan, reorder, compress: fix the sequence while the pages are still separate and easy to recognize, then squeeze the file down for email or upload limits. Trying to identify pages in an already-compressed scan is much harder, because compression blurs exactly the small text you would use to tell one page from another.
Use cases: five times a page shuffle fixes the whole job
- A tax packet assembled in a hurry. Receipts, statements and the summary page land in the scanner tray in whatever order they were in the envelope. Reorder so the summary comes first, then send one tidy PDF instead of apologizing for the mess.
- A contract returned with the signature page in the middle. Move the signature page to the end, or to the front if your reviewer expects it there, without asking anyone to re-sign or re-scan anything.
- A teacher building a worksheet packet. Pull the answer key out of the back by deleting it, shuffle the practice pages into difficulty order, and hand students a clean packet while the full version stays on your drive.
- A thesis draft with the appendix in the wrong spot. Chapter order changes weekly during writing. Moving whole pages is faster and safer than exporting to a word processor and hoping the layout survives.
- A bid package where each vendor's pricing must come last. Delete the pricing pages from the shared copy so the technical reviewers never see them, keeping the confidential original untouched for the final merge.
The same logic applies whenever a document's meaning depends on sequence: minutes before attachments, exhibits before the summary, plot boards before the script. If a human is going to read it in order, the order is part of the content. More PDF fixes live on our blog, including a walkthrough of splitting a PDF into separate pages and a guide to extracting pages from a chapter or contract.
What we actually tested
This page makes specific claims, so here is how they were checked. Open DevTools, go to the Network tab, drop a PDF, reorder it and export: the only requests you see are the page's own HTML, CSS and JavaScript, plus the two library files fetched the first time you open a PDF. Nothing uploads, because the path runs through pdf.js and pdf-lib entirely inside your tab.
On losslessness: we reordered a text-heavy report and checked the output by selecting and copying a paragraph, then searching for a word on the last page. Both behaved exactly as in the original, which is what "copied page objects" should mean. On deletions: removing a page in the middle did not renumber or rescale anything, and mixed-size documents kept each page's own dimensions. On ordering: reverse, reset and single-step moves all produced the sequence shown on the cards, and the position labels matched the export every time.
Two honest details from testing. First, a 200-page scanned PDF takes real time to render thumbnails (the progress bar tells you where it is), while the export itself is quick. Second, the output is frequently a few percent smaller than the input, which comes from rebuilding the file structure rather than from any quality change, and it is the same effect the PDF Merger produces. We also confirmed the Network tab stays idle during a full reorder on a file with embedded fonts and internal links.
Limits: what this reorder tool won't do, and why
An honest list beats a surprised user:
- Password-protected PDFs are refused. Encrypted files cannot be opened by browser JavaScript, so the tool reports the problem instead of failing halfway. Remove the password in a desktop app, or Print to PDF to make an unlocked copy, then reorder that copy.
- Interactive form fields may lose their appearance. Page content is copied, but widget annotations (the clickable form boxes) are not rebuilt. If your file is a fillable form, keep the original as your master.
- Bookmarks and attachments stay behind. pdf-lib copies pages, not the document-level outline and embedded-file lists. For most reorder jobs that list is empty anyway, but if yours is not, archive the original.
- One file per run. The tool handles a single PDF at a time on purpose: merging and reordering in one step is two tools' jobs, and doing both at once makes it harder to see what changed. Use the PDF Merger for the combine step.
- Huge files are bounded by your device memory. Everything is held in the tab, so a very large scan may be slow or may fail on a phone. The same file on a laptop usually works fine.
- Thumbnails are previews, not proof. They render at about 150 pixels wide, so fine print looks like a gray blur. Use the page number label, not the preview text, when you need certainty.
Need to shrink, split or combine instead? Those live on the Tools page, and the basics of why PDFs grow in the first place are covered in how to compress a PDF without losing quality.
Also fixing a PDF right now?
The PDF Compressor shrinks a PDF after you've fixed its order: same privacy, same speed, no quality slider to guess at.
Open PDF Compressor